
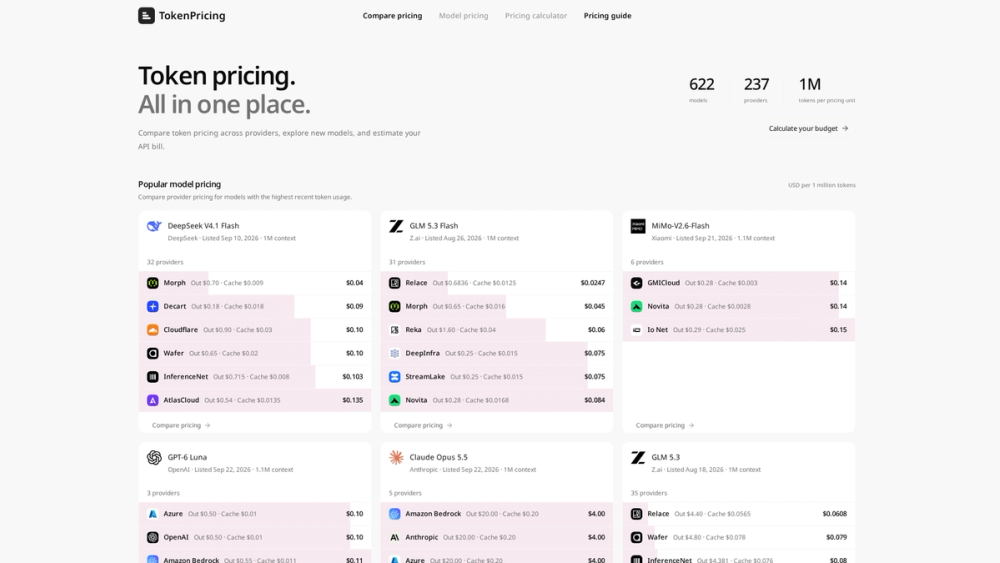
TokenPricing is a free, independent LLM API pricing comparison site: "Token pricing. All in one place." It lets you compare token pricing across providers, explore newly listed models and estimate your API bill, with no signup or login.
The homepage counter currently shows 622 models and 237 providers. All rates are in US dollars per 1 million tokens, with input, output and cache-read pricing kept separate, so an official developer price, a cloud listing such as Amazon Bedrock, Azure or Google, and an inference host such as DeepInfra, Novita or Together can be compared directly.
How the data is handled
- Pricing covers standard, global, default-group API usage.
- Each offer links to the page where its pricing was published. The first row for a model is its base rate; other rows are additional provider pricing.
- Missing pricing remains unknown and a reported zero stays zero; a dash means "not reported", not free.
- Only active, standard base token rates are included; batch, region-specific, VIP-group and token-tier offers are excluded.
- Price outliers and offers with unverified currency conversion are flagged and left out of price summaries.
Compare pricing (homepage)
"Popular model pricing" cards cover the models with the highest recent token usage and list their cheapest offers. The "Compare model pricing" table shows one row per model with date, provider, context window and input, output and cached price. Rows expand to show every offer, and the table can be searched and filtered by 30 days, 90 days or all time, based on each model's release or listing date. A "Calculate cost" link on each row opens the calculator with that offer preloaded.
Model pricing (/models)
Models are grouped by developer, currently 23 models from 13 developers including Anthropic, DeepSeek, Google, Meta, NVIDIA, OpenAI, Xiaomi and Z.ai. Each card shows listing date, provider count, context window and official input and output price. Subscription-only models are labeled as such instead of getting an invented token price.
Model pages
Each model page shows official pricing, the lowest input price and its provider, context window, capability tags (Tool Use, Reasoning, Caching, Structured Output) and the weight license. A scatter chart plots input against output price, with dashed lines marking official pricing, so points down and to the left are cheaper on both. Provider tables add cache-read, blended price, cache write, web search fees, speed and uptime where published, plus percentage versus official pricing, API connectivity, model availability, model IDs and the provider's Ahrefs domain rating. Blended price assumes three input tokens per output token with half the input read from cache. Listings with a domain rating under 10 are omitted.
Pricing calculator (/calculator)
Choose published model pricing or enter custom rates, then set input tokens, output tokens, requests per month and cache hit rate, or start from the Chat app, AI agent or High volume preset. You get estimated monthly cost, cost per request and an uncached/cached/output breakdown, plus a comparison of the same workload across other offers. The formula is shown on the page, along with tips on measuring real usage, counting reasoning tokens and assuming realistic cache hit rates. Estimates exclude taxes, cache writes and storage, request fees and other non-token charges.
Pricing guide
Linked from the main navigation, the guide covers pricing units, traceable sources, the dataset license and pricing conditions, including the note that capabilities are reported metadata, not a performance benchmark.
Who it is for
- Developers picking the cheapest provider for a model
- Teams budgeting an AI app or agent before launch
- Anyone checking how prompt caching changes the bill
TokenPricing is free, with no paid plans and no account needed. The site is in English with light, dark and system themes. Contact: team@tokenpricing.co.


